A broken link checker for multiple WordPress sites that walks each one the way a visitor would
About once a week ReDock Web walks every connected WordPress site the way a visitor would and lists each link that answered with an error, the page it sits on, and the links it could not check.
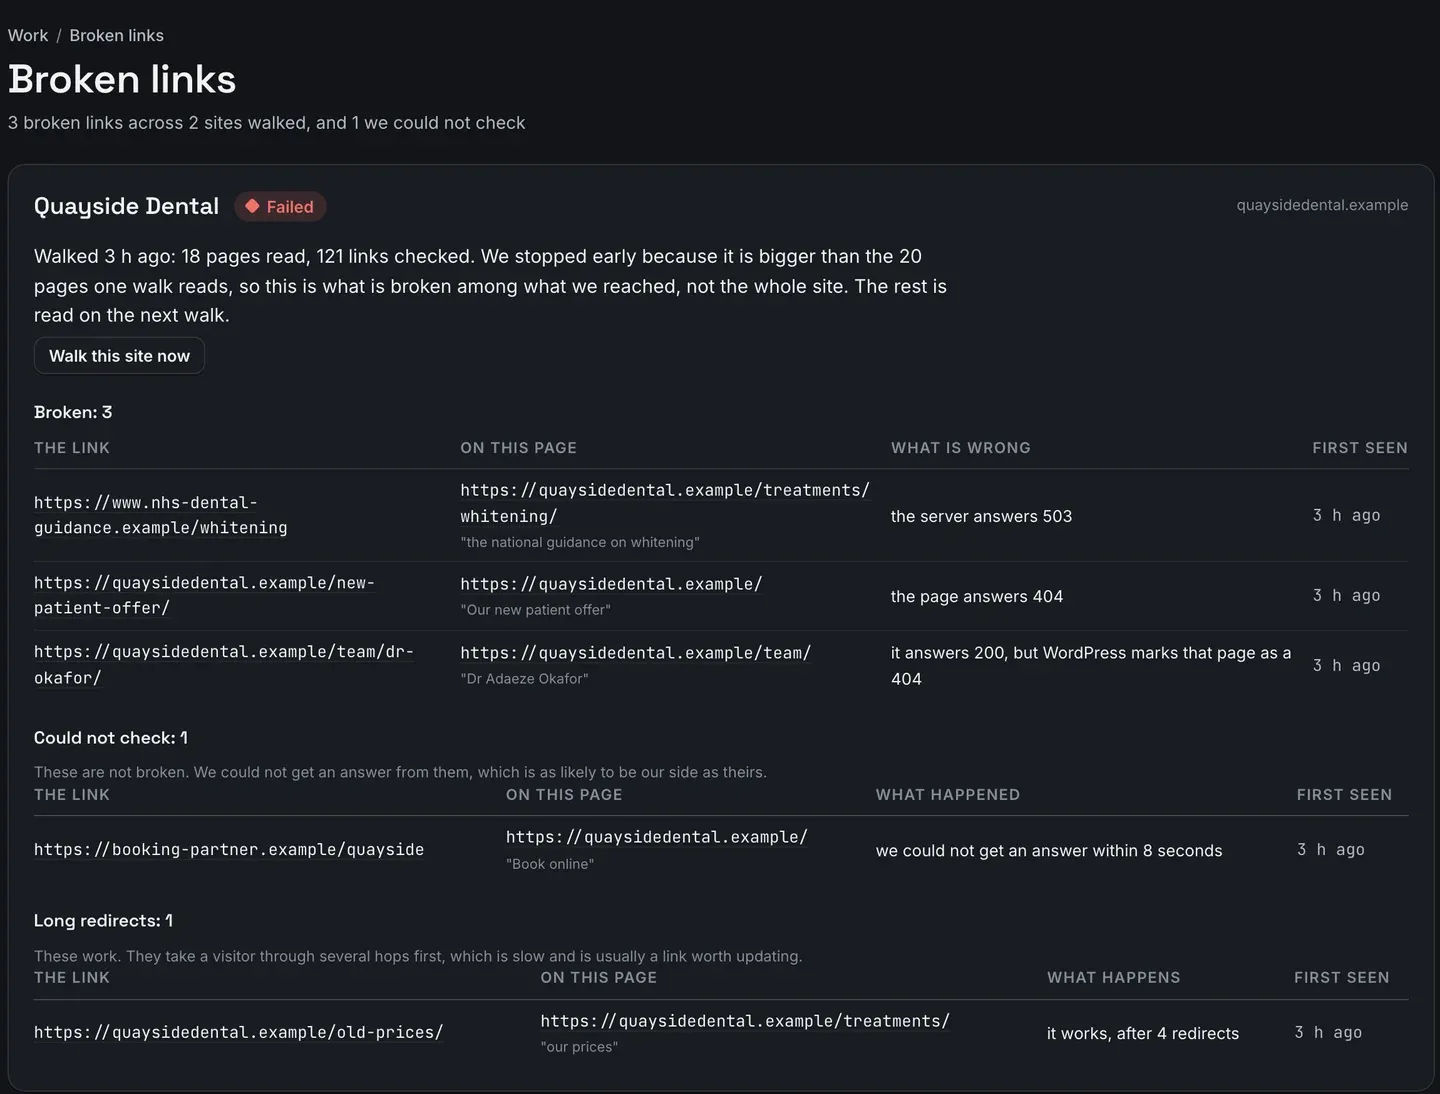
A broken link checker for multiple WordPress sites has to do what a visitor does, on every client site, without anybody remembering to run it. ReDock Web walks each connected site about once a week. It reads the pages, follows the links, and lists every link that answered with an error, with the page it was found on and the words the link used. Links that gave no answer are listed separately and never counted as broken, and so are links that only work after four or more redirects. The walk is an ordinary visit to the public site: it honours robots.txt, sends one request at a time, and names itself on a public page any host can read. This post reads one week’s walk, fixes what it found, and looks at a site that asks crawlers to stay out.
What counts as broken, and what does not
A link is broken when it answers 404 or a server error. A page on the site that answers 200 while WordPress itself marks it as not found counts too. If the only sign is the page’s title, the list says so and quotes the title, because a title is weaker evidence than WordPress’s own mark.
These are deliberately not counted:
- A link that gave no answer, a server that asked the walk to slow down, or one that timed its own request out. Those go under Could not check, because the cause is as likely to be on ReDock’s side as the site’s.
- A page on somebody else’s site that answers 200. Other sites are asked for their headers only, never for the page.
- A theme’s own friendly not-found page that answers 200 without WordPress’s mark. Telling that apart from a real page would mean guessing at words.
- A missing address that redirects to a real page. Whether it is the right page is not something a crawler can know.
A link that works after four or more redirects is listed as a long redirect. It is not broken, but every hop is a wait for the visitor, and it is usually worth updating.
The task: one week’s walk, read and fixed
1. Open Broken links
It sits under Work in the sidebar. The line under the heading adds up the broken links across the sites walked and the ones that could not be checked, and each site gets a card. The picture at the top of this post is one of them.
2. Read the site’s card
The card says when the site was walked and how much of it was read. One walk reads up to 20 pages and checks up to 150 links, so a bigger site is covered over several walks. Its card says the walk stopped early, that the list is what was found among the pages it reached, and that the rest is read next time.
Then come up to three tables:
- Broken: the link, the page it is on with the link’s own words under it, what is wrong, and when it was first seen.
- Could not check: links that gave no answer, with what happened.
- Long redirects: links that work after four or more hops.
Two details make the list useful for client work. A broken link keeps the date it was first seen for as long as it stays broken, so you can say how long it has been that way. And the same dead link on four pages makes four rows, one for each place it needs fixing.
3. Open the site’s own page
When a site has more findings than its card shows, See all opens that site’s page, with every finding and a table of its last walks. ReDock keeps the last eight.
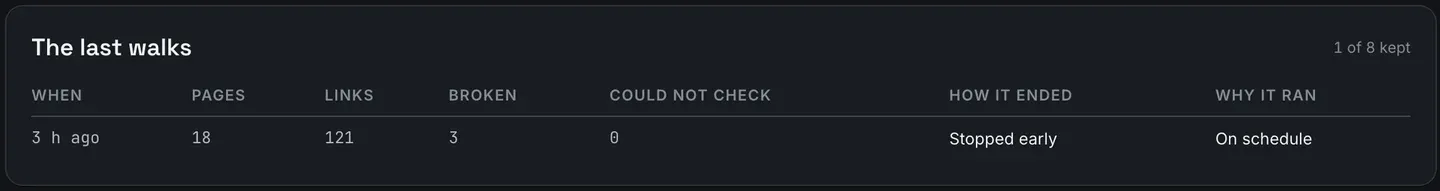
Read the How it ended column before telling a client their site is clean. A walk that stopped early has only looked at the pages it reached.
4. Fix the link on the page it names
Edit the page, or the menu or widget that carries the link. The next walk that reads that page and finds the link working takes it off the list. A walk that stopped early never takes a link off, because it has not looked at the pages it did not reach.
5. Walk the site again, if it cannot wait
Walk this site now moves the site to the front of the queue, and the walk runs within the hour. Otherwise each site waits its turn, about six days, and the one that has waited longest goes first. A newly connected site gets its first walk within the hour anyway.
A site that asks crawlers to stay out
Some client sites block crawlers in robots.txt. Google’s introduction to robots.txt describes the file as telling crawlers which addresses on a site they may access, and the walk treats it exactly that way.
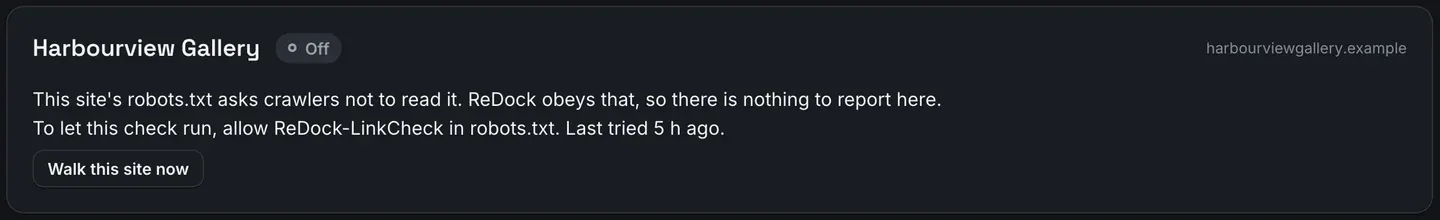
The card says so plainly instead of showing a clean result, and tells you what to change: allow ReDock-LinkCheck in robots.txt. An address that robots.txt rules out is never fetched and never reported.
A site whose front page asks for a password, as a staging site or a firewall might, gets the same honest treatment. The walk stops at the front door and says so, rather than reporting a site full of broken links.
When a hosting company asks what it is
The walk is gentle by design: one request at a time, never two at once, and at least 300 milliseconds between requests to the same server, longer when the site’s robots.txt asks for it with Crawl-delay. It still shows up in access logs, so every request names itself as ReDock-LinkCheck, along with the address of a public page.
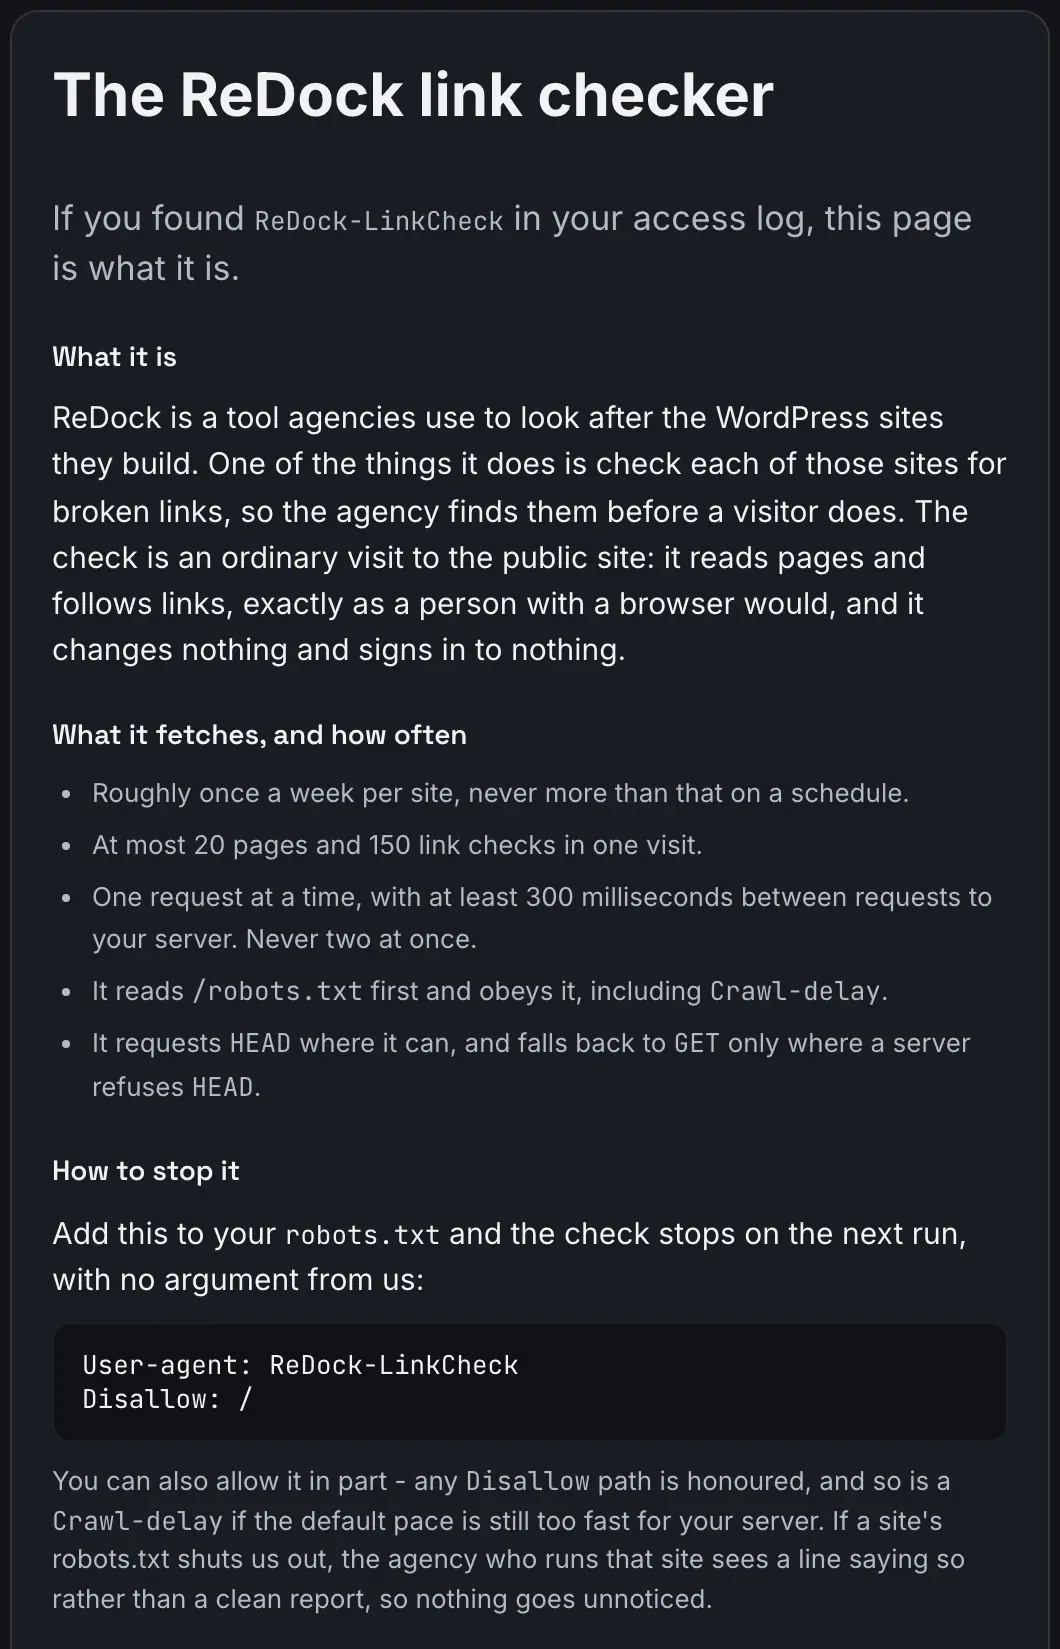
Nobody needs an account to read it, which makes it the link to send a host’s support team. To stop the check on one site, two lines in that site’s robots.txt do it:
User-agent: ReDock-LinkCheck
Disallow: /
The rules, the limits and the refusals are all in the link checks guide.
FAQ
Does the link check need a plugin on the site?
The walk is an ordinary visit to the public site, so it works whether or not the site has ReDock Connect on it. The site does need to be one of the connected sites in your workspace.
How often is each site walked?
About once a week. Each site waits its turn, roughly six days, and the one that has waited longest goes first. Walk this site now runs one within the hour.
Will it slow a client’s site down?
It sends one request at a time, with at least 300 milliseconds between requests to the same server, and honours Crawl-delay. Links to other sites are asked for their headers, not their pages.
Why is a link I know is dead listed under could not check?
Because it gave no answer rather than an error. A missing answer is as likely to be ReDock’s side as the site’s, so it is never called broken.
Walk one site this week
A free account connects one live WordPress site, and the link walk runs on it with no setup. Connect the site with the most pages and read its card after the first walk.
Create a free account and find the links your client’s customers are already hitting.